1. The Problem: AI Agents Are Getting Too Expensive
Right now, AI agents are hitting a financial wall.
- Tools like OpenClaw run continuously
- They store huge histories + tool outputs
- Context keeps growing → millions of tokens burned weekly
Result: Developers are paying thousands of dollars per month
And it gets worse with premium models:
- Anthropic’s Claude Opus → ~$25 per million tokens (up to $150 for fast responses)
Core problem: You can’t scale agents economically using closed APIs alone
2. The Shift: Smart Routing + Open Models
Because of cost:
-
hybrid systems
- Small tasks → cheap/open models
- Hard tasks → powerful models
This is called: Smart routing architecture
3. Why is nvidia doing this? (The Strategic Move)
The open AI world is unstable right now:
- Meta slowing Llama releases
- DeepSeek facing training issues
- Alibaba’s Qwen team uncertain
Gap in leadership
4. Nemotron 3 Super
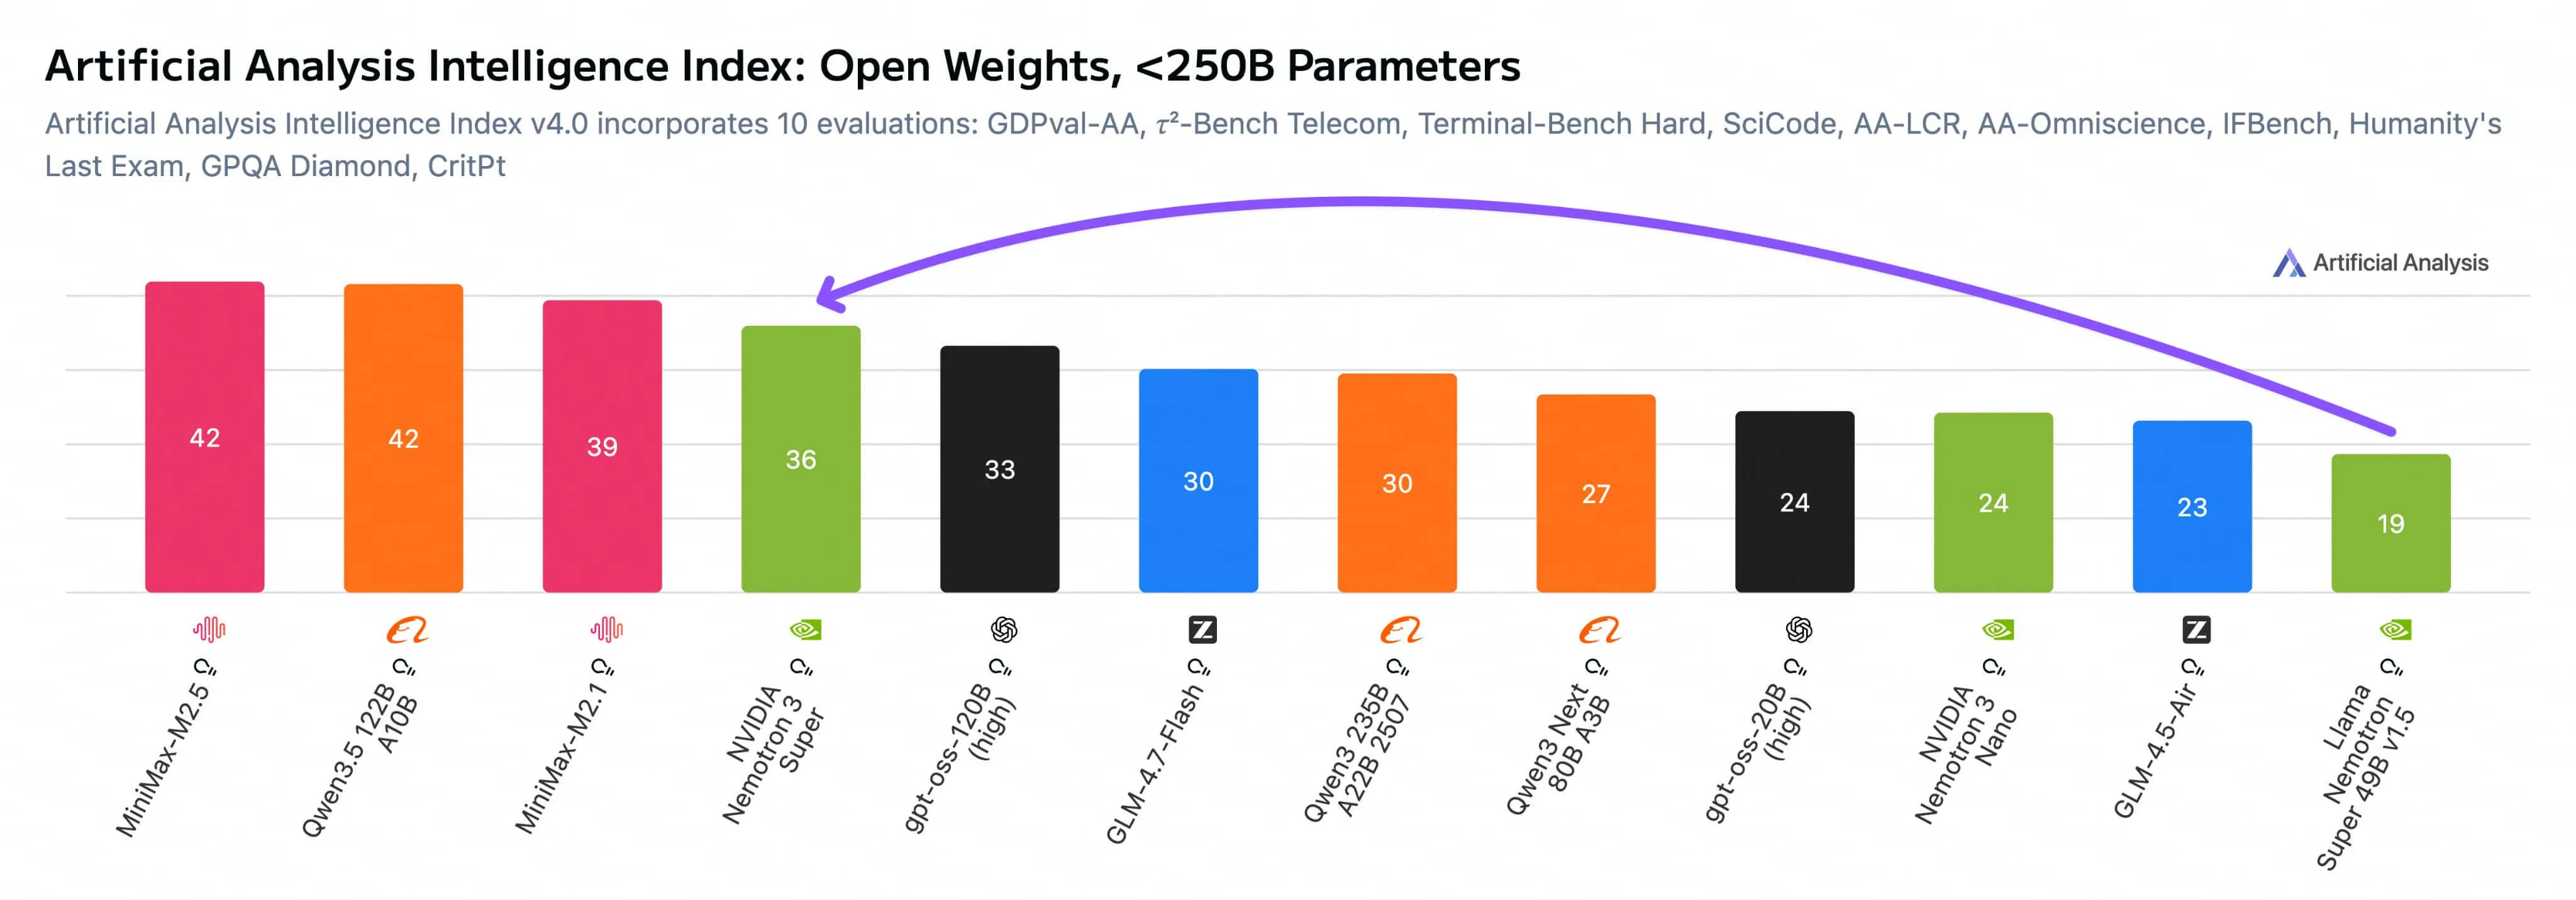
- 120B parameters (MoE model)
- Only ~12B active at a time → efficient
- 1 MILLION token context
Hybrid Mamba + Transformer
- Normal transformers = expensive for long context
- Mamba reduces memory usage
- Handles long conversations cheaply
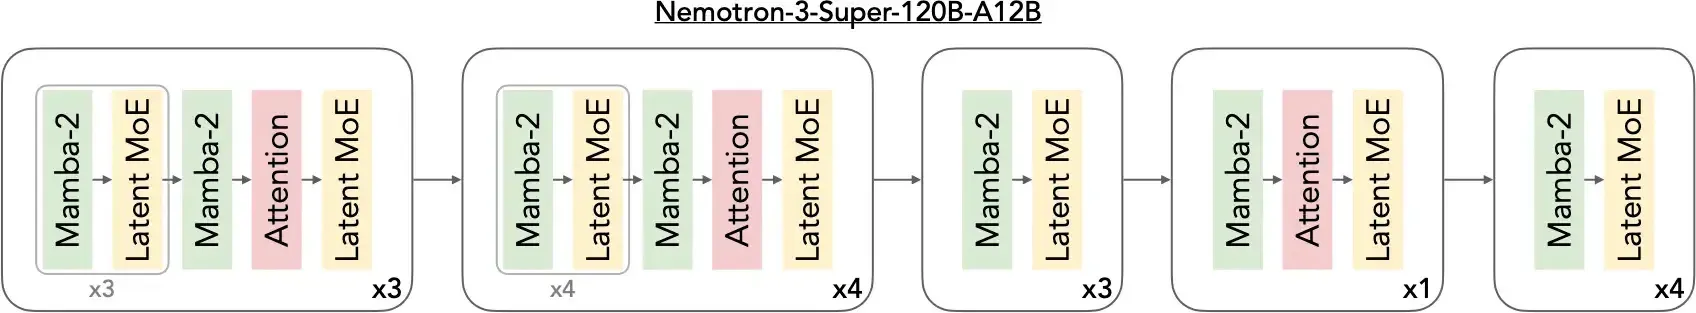
Latent MoE
- Uses experts in compressed space
- Less communication overhead
- More accuracy, same compute cost
Multi-token Prediction
- Predicts multiple tokens at once
- Faster responses + better reasoning
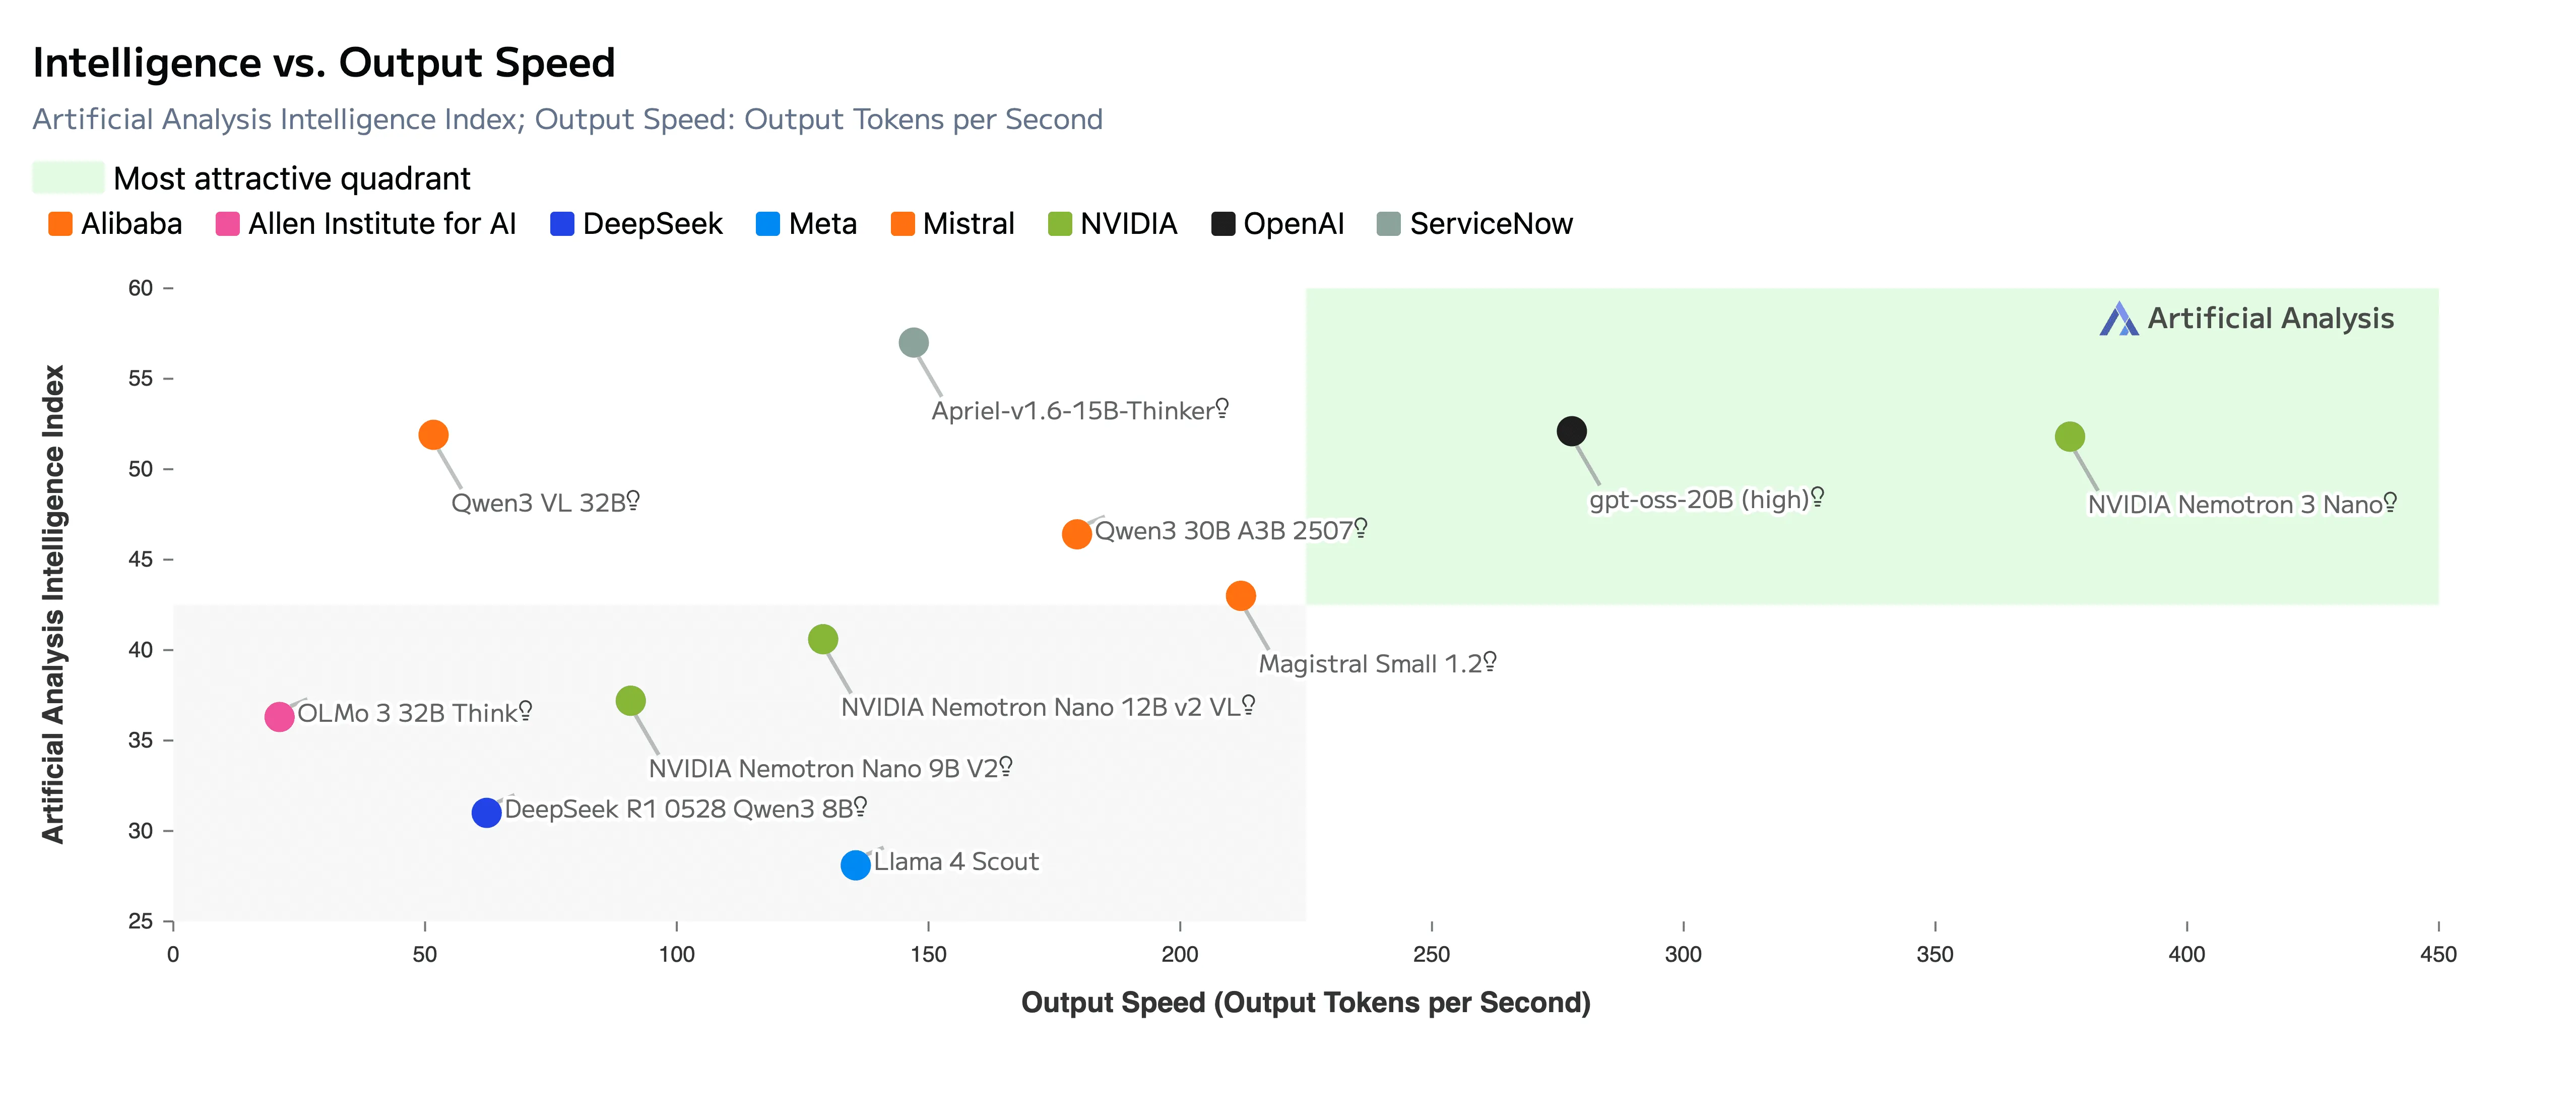
So Nvidia also made:
- 30B model
- 4B lightweight model
| Task | Model |
|---|---|
| Simple steps | Nano |
| Complex reasoning | Super |
5. Nvidia’s Genius Business Strategy
Most companies:
- Release open models → marketing
- Make money from APIs
But Nvidia is different: They make money from hardware
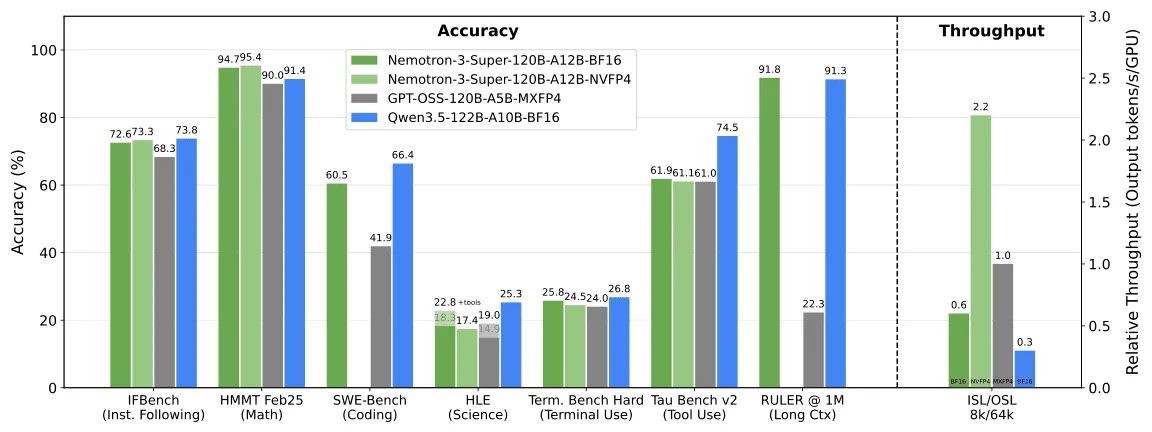
Hardware + AI Co-Design
- New GPUs: Blackwell B200
- Special format: NVFP4 (4-bit)
Benefits:
- 2x speed
- Lower cost
- Same accuracy
And Nemotron is built for this hardware
So:
If you want best performance → you must use Nvidia GPUs
6. The $26 Billion Flywheel
Nvidia is investing:
💸 $26 billion in open AI models
Why?
To create a loop:
- Developers use Nvidia models
- They optimize for Nvidia hardware
- More GPU demand
- Nvidia makes more money
This is called a developer flywheel